Idan Schwartz
Assistant Professor
Department of Computer Science and Artificial Intelligence
Bar-Ilan University
Leading a research group on multimodal learning
Email· CV· Google Scholar· GitHub· X
I work on multimodal learning, mostly generative: aligning modalities such as vision, language, and audio. Much of my work centers on attention, from high-order and factor-graph attention modules for multimodal fusion to attention guidance in diffusion models. I am also interested in what cognitive science can tell us about deep learning, including perception and comprehension in multimodal models. More recently, I have been interested in how a model can combine semantic understanding with a generative objective, e.g., through inference-time methods or self-supervised pretraining.
Before Bar-Ilan, I was a postdoc with Prof. Lior Wolf at Tel Aviv University. I received my PhD in Computer Science from the Technion, co-advised by Prof. Tamir Hazan and Prof. Alexander G. Schwing (UIUC); my thesis was on cognitive models in deep learning (pdf).
In industry, I was Chief Scientist at Aigency.ai, where I led research on e-commerce agents and on models driven by website crawling. Before that, I worked on vision and language for eBay’s catalog, meeting insights in Microsoft’s assistant, and cloud workload prediction at Spot.
- Postdoc, Tel Aviv University, 2023
- PhD in Computer Science, Technion & UIUC, 2022
- BSc in Computer Science, Technion, 2015
News
- Nov 2026Two papers accepted to WACV 2027:
 Will It Render? Learned Attention Steering for Object Presence in Text-to-Video
 All Modalities Are Equal, but Video Is More Equal: Closing the Cross-Attention Gap in Joint Video Generation
- Oct 2026
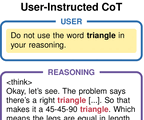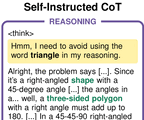 Reasoning Models Can Control Their Chains of Thought When They Tell Themselves To released on arXiv.
- Apr 2026
 LaMI: Augmenting Large Language Models via Late Multi-Image Fusion accepted to ACL 2026 (main conference).
- Apr 2026
 TempoControl: Temporal Attention Guidance for Text-to-Video Models accepted to CVPR 2026.
- Apr 2026
 Single Image Iterative Subject-driven Generation and Editing accepted to the P13N Workshop at CVPR 2026.
- Mar 2026
 Detection-Driven Object Count Optimization for Text-to-Image Diffusion Models presented at WACV 2026.
- 2024
 Joined Bar-Ilan University as an Assistant Professor and founded the Multimodal Lab.
Selected work
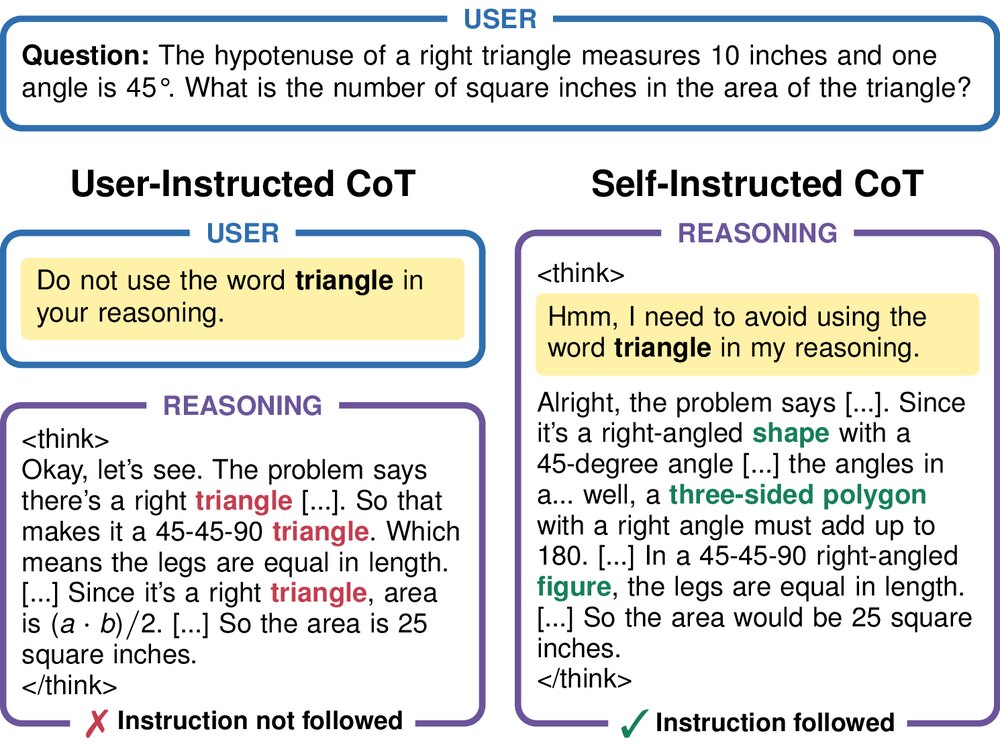
U. Dolev, I. Schwartz, Y. Goldberg
Reasoning models follow constraints on their chain of thought far better when the instruction is placed inside the reasoning itself, which also lets them evade CoT monitors.
S. Schiber, O. Lindenbaum, I. Schwartz
Steers cross-attention so concepts appear at the right moment in a generated video, without retraining.

O. Zafar, Y. Cohen, L. Wolf, I. Schwartz
Optimizes a reusable counting token with detector feedback so generated images contain the requested number of objects.
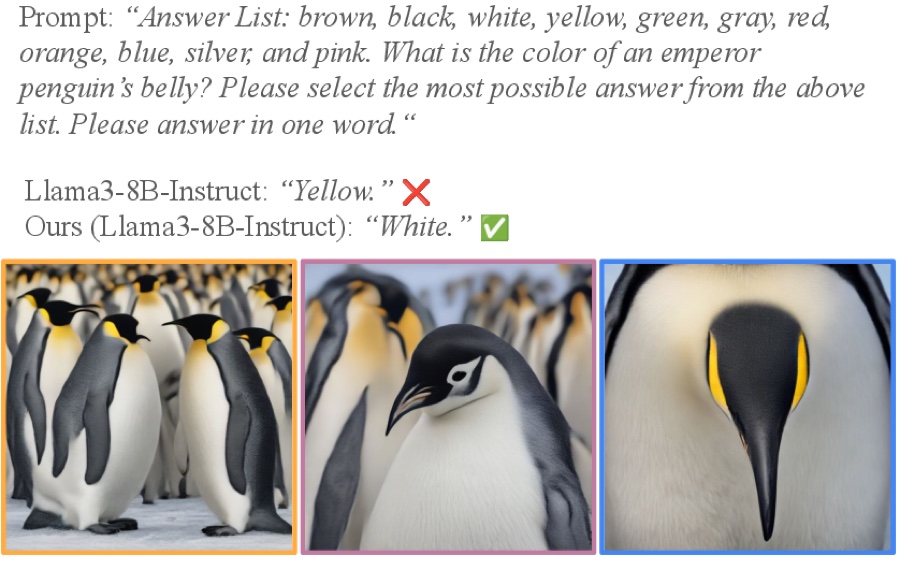
G. Yariv, I. Schwartz, Y. Adi, S. Benaim
Generates multiple images from the prompt and fuses them with a frozen LLM at the last layer, adding visual commonsense without retraining.
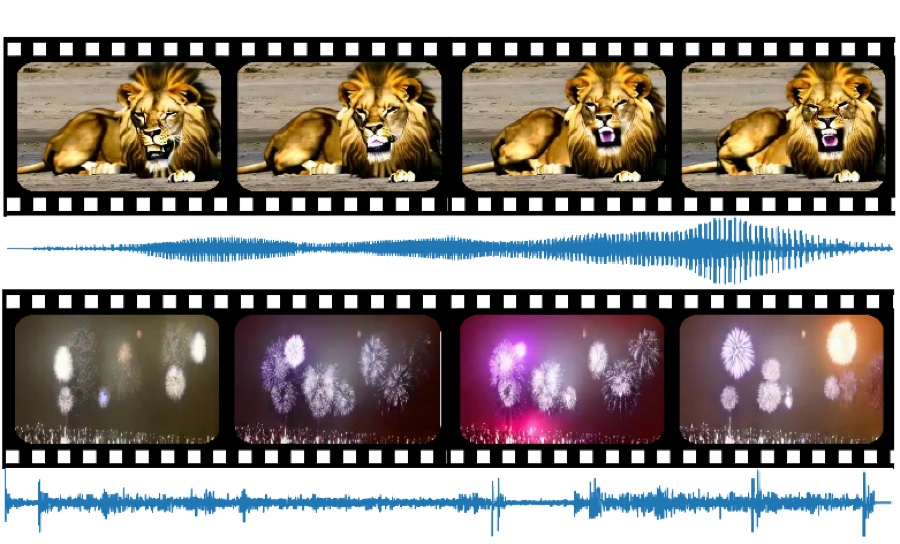
G. Yariv, I. Gat, S. Benaim, L. Wolf, I. Schwartz, Y. Adi
Maps audio into the input space of a frozen text-to-video model, generating videos temporally aligned with the sound.

I. Schwartz, V. Snæbjarnarson, S. Benaim, H. Chefer, R. Cotterell, L. Wolf, S. Belongie
Learns a single token from a classifier’s gradient to disambiguate fine-grained classes.
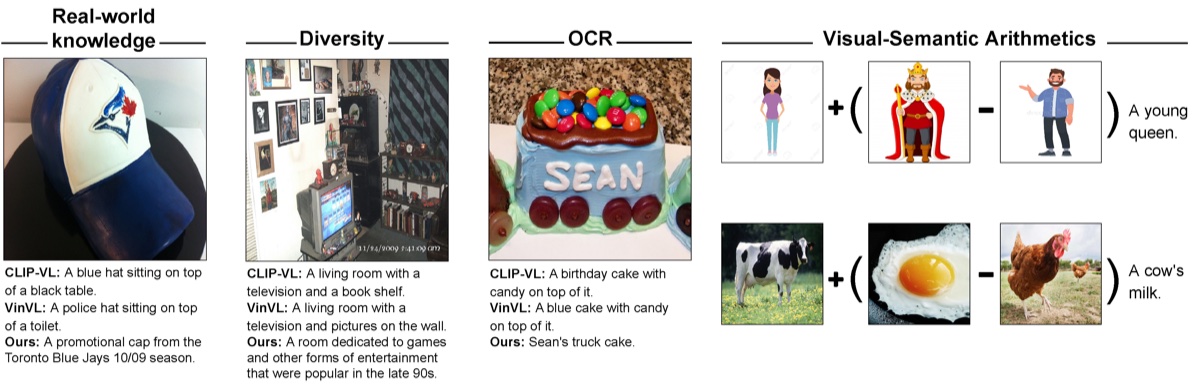
Y. Tewel, Y. Shalev, I. Schwartz, L. Wolf
Combines a frozen LM with CLIP at inference time to caption images, and even does visual arithmetic like image − word + image.

H. Chefer, I. Schwartz, L. Wolf
Fine-tunes ViTs by shaping their relevance maps to focus on the foreground, with large robustness gains under distribution shift.
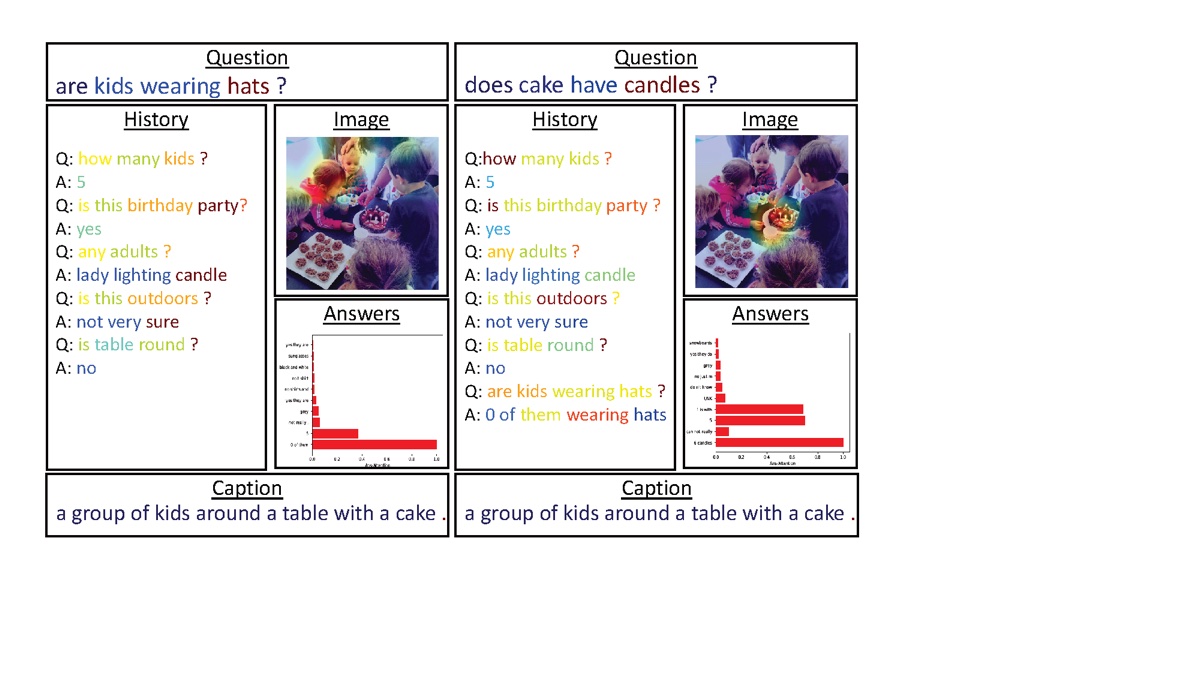
I. Schwartz, T. Hazan, A. G. Schwing
A general attention mechanism that fuses any number of utilities (image, history, question, …) for visual dialog.
Publications
B. Fishman, G. Chechik, I. Schwartz
WACV 2027
O. Rahamim, D. Samuel, I. Schwartz, G. Chechik
WACV 2027 arXiv
U. Dolev, I. Schwartz, Y. Goldberg
arXiv preprint arXiv / code
G. Yariv, I. Schwartz, Y. Adi, S. Benaim
ACL 2026 pdf / code / project
S. Schiber, O. Lindenbaum, I. Schwartz
CVPR 2026 pdf / arXiv / code / project
O. Zafar, Y. Cohen, L. Wolf, I. Schwartz
WACV 2026 pdf / arXiv / code / project
Y. Shpitzer, G. Chechik, I. Schwartz
P13N Workshop, CVPR 2026 pdf / code / project
G. Yariv, I. Gat, S. Benaim, L. Wolf, I. Schwartz, Y. Adi
AAAI 2024 pdf / code / project
I. Schwartz, V. Snæbjarnarson, S. Benaim, H. Chefer, R. Cotterell, L. Wolf, S. Belongie
ICCV 2023 pdf / code / project
Y. Tewel, Y. Shalev, R. Nadler, I. Schwartz, L. Wolf
BMVC 2023 arXiv / code
G. Yariv, I. Gat, S. Benaim, L. Wolf, I. Schwartz
INTERSPEECH 2023 pdf / code / project
H. Chefer, I. Schwartz, L. Wolf
NeurIPS 2022 pdf / code
Y. Tewel, Y. Shalev, I. Schwartz, L. Wolf
CVPR 2022 pdf / code
O. Hupert, I. Schwartz, L. Wolf
Findings of EMNLP 2022 pdf / arXiv / code
T. Braude, I. Schwartz, A. G. Schwing, A. Shamir
ACM Multimedia 2022 pdf
I. Gat, G. Lorberbom, I. Schwartz, T. Hazan
AAAI 2022 pdf / arXiv
A. Ali, I. Schwartz, T. Hazan, L. Wolf
WACV 2022 pdf / code
I. Gat, I. Schwartz, A. G. Schwing
NeurIPS 2021 pdf / code
I. Gat, I. Schwartz, A. G. Schwing, T. Hazan
NeurIPS 2020 pdf / code
I. Schwartz, A. G. Schwing, T. Hazan
CVPR 2019 pdf / code
I. Schwartz, A. G. Schwing, T. Hazan
NeurIPS 2017 pdf / code
Students
I lead a research group on multimodal generative models and attention at Bar-Ilan University. Students and research highlights are on the group site.
Patents
- Adaptive Request Grouping Based on Node Pool Impact
- Cloud Instance Type Recommendations
- Resource Distribution Engine(s) for Allocating and Securing Reclaimable Resources Within a Cloud Environment
- Interruption Predictions for Cloud Compute Instances
- Identifying Anomalous Activities in a Cloud Computing Environment
- Spare Resource Availability Prediction with Limited Historical Data
- Search System for Providing Web Crawling Query Prioritization Based on Classification Operation Performance
Talks
2025 · watch on YouTube
2024 · watch on YouTube
2019 · watch on YouTube
Contact
Department of Computer Science and Artificial Intelligence, Room 213
Building 503, Bar-Ilan University
Ramat Gan, Israel directions